5 Stages for Practitioner Data Lineage: PROV, Automation, Embedded AI
Practical steps to instrument data lineage tracking: five stages using W3C PROV and OASIS DPS, start with automation and include embedded AI patterns.
On this page
Data lineage tracking records where each piece of data came from and how it changed as it moved through your systems, so teams can debug faster, prove compliance, and run safe impact analysis before touching a pipeline. Full coverage rarely comes from automation alone; most working programs blend automated capture with targeted manual annotation for the systems automation can’t reach. The payoff shows up first in root-cause analysis and second in audit readiness.
TL;DR:
- Most organizations should start with table-level lineage capture for speed and simplicity, then add column or record-level tracking for sensitive or high-stakes data.
- Automated lineage methods like query parsing, CDC, and native pipeline tools work best when combined, but legacy systems often require manual annotation first for accurate mapping.
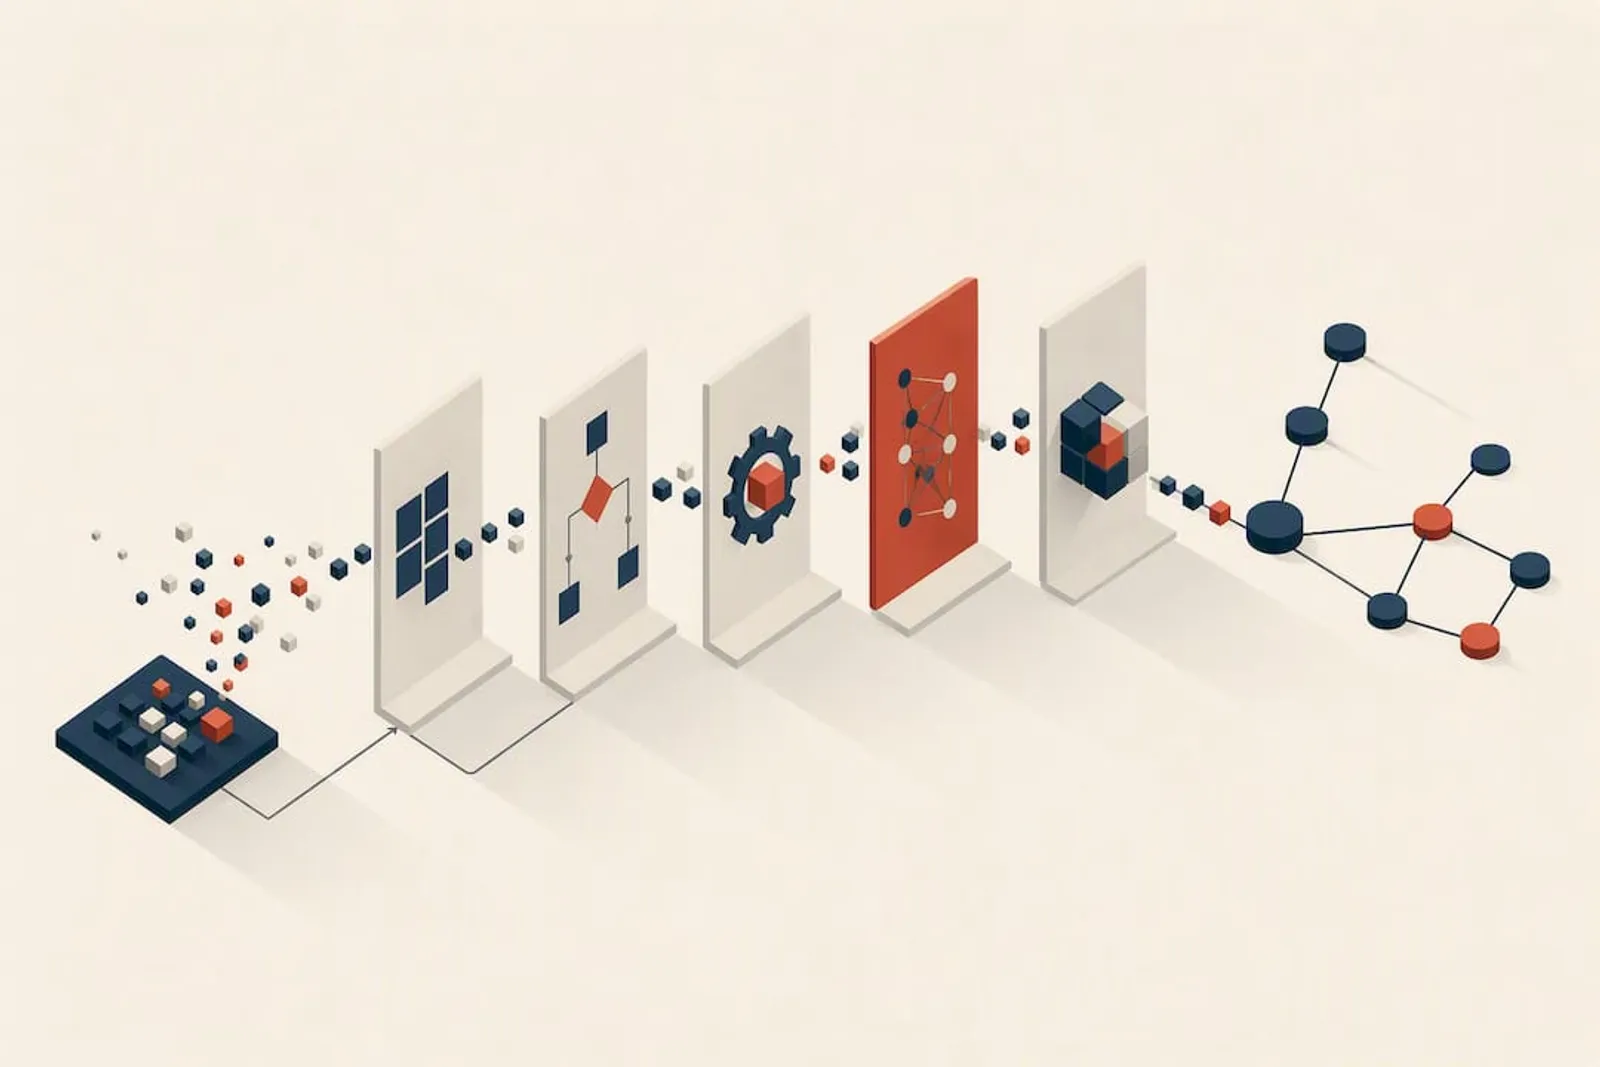
- End-to-end lineage flows through five stages: capture, normalization, enrichment, storage, and querying, with coverage gaps often caused by unconfigured connectors.
- Impact analysis for schema changes and root-cause analysis for errors rely heavily on accurate backward and forward lineage, respectively, reducing resolution time significantly.
- Adopting standards like W3C PROV and OASIS DPS ensures consistent, auditable metadata, especially crucial for compliance and AI model reproducibility.
What Is Data Lineage Tracking, and How Granular Should It Get?
Data lineage tracking is often confused with two related terms. Data provenance refers to the origin story of a specific data element (who created it, when, and by what process), which maps closely to the W3C PROV model’s entities, activities, and agents. Data traceability is the operational ability to follow that history end-to-end when something breaks. Data lineage tracking is the practice that produces both: the metadata graph that makes provenance queryable and traceability possible.
Teams building a data lineage management program need to pick granularity deliberately, since capturing everything at the finest level is expensive and often unnecessary.
- Dataset or table level shows which tables feed which reports. This is fast to implement and usually the right starting point.
- Column or field level tracks individual attributes across transformations. It costs more to build but is essential for personally identifiable information (PII), financial fields, and anything touching model training data.
- Record or event level traces individual rows or events, typically reserved for high-stakes compliance investigations.
Direction matters too: backward lineage answers “where did this number come from,” forward lineage answers “what breaks if I change this,” and end-to-end lineage connects both across the entire pipeline. Column-level lineage earns its cost around PII and regulated fields; table-level is usually sufficient everywhere else.
Automated Capture vs. Manual Data Lineage Tracking: Which Approach Fits?
Most data lineage software uses several automated capture techniques, and modern lineage systems typically combine more than one rather than relying on a single method.
- Query parsing reads SQL logs or execution plans to reconstruct table and column relationships without touching production code.
- Log and change-data-capture (CDC) extraction watches database transaction logs or streaming events to infer lineage from actual data movement.
- Pipeline-native capture pulls lineage directly from orchestration metadata, the approach tools like dbt and Airflow support natively through their own execution graphs.
- API-driven collection queries platform metadata APIs (warehouse catalogs, BI tool APIs) to assemble lineage from system-reported relationships rather than inferring it.
Inference itself splits into pattern-based matching (naming conventions, schema similarity), parsing-based extraction (actual code and query analysis), and manual tagging or annotation for undocumented logic. Legacy systems and black-box vendor tools usually can’t be parsed automatically, which is where hybrid or fully manual data lineage tracking still earns its place. A spreadsheet macro or a stored procedure nobody has touched in six years won’t expose its logic to any parser.
Pro Tip: Don’t try to automate lineage for a legacy system on day one. Document it manually first, even in a shared spreadsheet, then automate once the manual map reveals which fields actually matter.
The trade-off is consistent across all four methods: parsing-based approaches give higher accuracy but narrower coverage, while pattern-based inference scales faster but produces more false positives you’ll need to review.
How Does Automated Lineage Tracking Work End to End?
A working lineage system moves through five stages, and understanding each one helps you diagnose where coverage gaps usually appear.
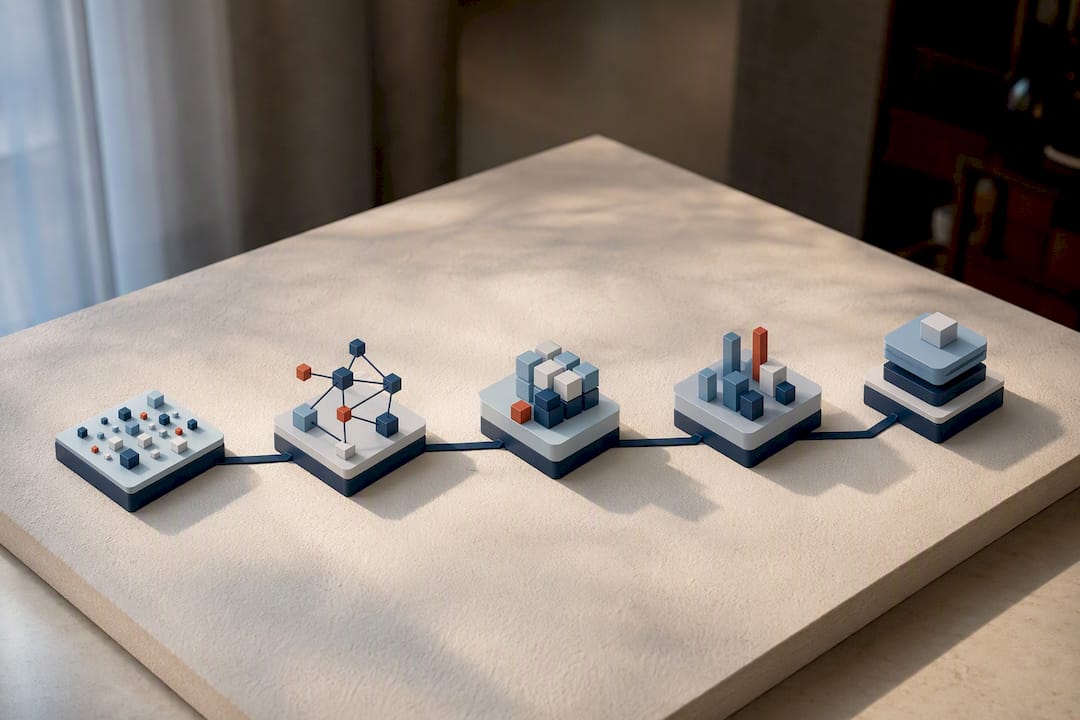
Capture starts with connectors pulling metadata from source systems: query logs, orchestration events, CDC streams, and API responses. Coverage gaps almost always trace back to a connector nobody configured for a specific data source.
Normalization maps raw capture output into a consistent graph model. This is where mapping to W3C PROV’s entities, activities, and agents pays off, because it gives every team a shared vocabulary instead of a dozen bespoke schemas. An entity is a piece of data, an activity is the transformation, and an agent is the system or person responsible. PROV also supports derivation and bundling constructs, letting you chain provenance and even express provenance-of-provenance when audits demand it.
Enrichment attaches schema definitions, business glossary terms, and sometimes the actual transformation code or SQL snippet to each graph edge. This step turns a technical graph into something a business stakeholder can actually read.
Storage and query typically use a graph database or a metadata catalog with graph indices, since lineage is fundamentally a graph traversal problem. Export formats matter for interoperability: PROV-JSON, OpenLineage’s format, DOT, and CSV are common choices that let you move lineage graphs between tools or archive them for audit purposes.
- Impact analysis queries walk forward from a table to find every downstream consumer.
- Root-cause queries walk backward from a broken dashboard to the source system.
- Visualization layers render the graph so engineers can spot a bad join without reading logs line by line.
Lightweight tools like dataprov demonstrate this whole pipeline can be scaled down: it captures file-level provenance in PROV-JSON with checksums and execution metadata, proving you don’t need an enterprise catalog to get real provenance.
What Are the Main Use Cases for Data Lineage Tracking?
Root-cause analysis is the use case most teams reach for first. When a dashboard shows a wrong number, backward lineage traces the exact transformation that introduced the error instead of triaging every job that touched the table that day. That difference typically cuts mean time to resolution from hours to minutes.
Impact analysis works the other direction. Before deprecating a column or changing a schema, forward lineage shows every downstream report, model, and pipeline that depends on it, which prevents the silent breakage that happens when nobody knew a finance dashboard depended on a field marked for deletion.
Compliance and auditable reporting depend on lineage as evidence. Regulators increasingly expect organizations to show, not just claim, where regulated data originated and how it moved. Data lineage management provides a documented trail to facilitate audit readiness.
ML and AI provenance is the newest addition to this list. Reproducing a model’s output requires knowing not just the training data but the preprocessing steps, feature transformations, and parameter versions applied at training time. Without that, a model retrained six months later can behave differently for reasons nobody can trace.
- Faster incident resolution through backward tracing
- Safer schema and pipeline changes through forward impact analysis
- Audit-ready compliance documentation
- Reproducible ML experiments and model provenance
- Reduced onboarding time, since new engineers can read the graph instead of asking around
Operational knowledge transfer might be the most underrated benefit: a new hire who can query the lineage graph learns a system’s architecture faster than one reading outdated documentation.
Implementing Data Lineage Tracking: A Prioritized Checklist
Rolling out lineage tracking across an entire data estate at once almost always stalls. A phased approach gets working coverage faster and builds credibility for expanding scope later.
- Prioritize by risk and impact. Start with sensitive or high-impact datasets such as regulated data, ML training inputs, and key reporting tables. Guidance from AWS’s Well-Architected framework specifically recommends focusing provenance capture on sensitive or high-impact datasets first rather than attempting uniform coverage.
- Set a coverage goal, not a completeness goal. Define a realistic coverage goal for critical pipelines in the initial deployment phase, and treat everything else as phase two.
- Automate first, annotate second. Deploy query parsing and pipeline-native capture wherever your stack supports it, then reserve manual annotation for the legacy systems automation can’t reach.
- Validate with the business owners, not just engineering. A lineage graph that’s technically correct but semantically wrong to a domain expert will get ignored. Sample a handful of edges and walk them through with the people who actually understand the data.
- Reconcile with a sampling audit. Pick a random set of downstream reports and manually verify the lineage graph traces to the correct source, catching parsing errors before they undermine trust in the whole system.
- Tie lineage to data quality and access controls. A lineage edge that shows a field flowing into a report should also flag if that field failed a quality check upstream, or if access permissions changed along the way.
- Assign ownership, SLAs, and retention rules. Someone needs to own the lineage metadata itself: who fixes broken connectors, how long lineage history is retained, and what the review cadence is.
Pro Tip: Measure success by the lineage graph’s practical usage for debugging, not just coverage metrics. A well-instrumented core with high query usage beats broad coverage nobody opens.
Which Standards Should Govern Your Lineage Metadata?
Two standards give data governance practices a shared vocabulary instead of ad hoc schemas that break the moment you need to share lineage data across tools or with an auditor.
W3C PROV models provenance as entities (data), activities (transformations), and agents (systems or people), with derivation and usage relationships connecting them. Mapping your lineage graph to these three constructs early prevents the common failure mode where every team invents its own metadata structure, then nobody’s structure talks to anyone else’s.
OASIS Data Provenance Metadata (DPS) specifies concrete fields to record for each provenance record: source, origin organization, generation date, and generation method. These fields turn an abstract lineage graph into something an auditor can actually verify.
Validation should combine automated and manual techniques:
- Checksum or integrity checks confirm a file or dataset hasn’t changed unexpectedly between capture and query.
- Sampling audits catch parsing errors that automated capture misses silently.
- Replay tests rerun a pipeline against captured lineage metadata to confirm the recorded transformation actually produces the claimed output.
Provenance chains and even provenance-of-provenance become necessary once a lineage graph feeds compliance decisions. Recording who validated the lineage and when is as important as recording the data movement itself.
Governance needs explicit roles (who owns lineage metadata), service-level agreements for connector uptime, change control for schema updates, and a defined retention period tied to your actual audit requirements.
Practitioner Patterns From Embedded AI Implementation Work
Instrumenting lineage for AI-driven workflows raises a wrinkle most generic guidance skips: you have to capture the data’s path without breaking the human-in-the-loop approval steps that make the workflow trustworthy in the first place. For AI-native compliance work, this means recording both the source data’s provenance and the preprocessing and parameter versions the model applied, so an output can be traced back and reproduced later.
Two recurring project patterns illustrate the trade-offs: property due-diligence workflows, where lineage needs to prove which source document generated a given clause in a report, and CE-marking compliance projects, where regulators expect a traceable path from raw input to certified output.
Common pitfalls worth flagging early:
- Over-instrumentation. Tracking every field “just in case” produces a graph too noisy to query usefully.
- Skipping domain validation. A technically correct graph that a compliance officer can’t confirm is semantically right isn’t finished.
- Brittle regex parsing. Pattern-based extraction breaks the moment source formatting changes, so pair it with monitoring that flags silent parsing failures.
Handover to platform teams should include documented connectors, a validated sample set, and clear ownership of ongoing maintenance.
Central Ownership or Embedded Delivery: Which Gets Lineage Working Faster?
Central data platform teams should own the standards: the schema you map to, the storage architecture, and the governance rules for retention and access. That’s where consistency across the organization actually gets enforced.
Embedded partners earn their keep in execution, particularly for the first high-priority domain or two, where deep familiarity with a specific pipeline’s quirks moves faster than a central team learning it from scratch. The strongest programs I’ve seen use a hybrid: platform teams set the PROV mapping and governance guardrails, while embedded specialists instrument the messy, domain-specific pipelines that a generalist platform team would take months to untangle. Neither model alone scales as well as the combination.
Theodor
Get Lineage Instrumented Without Losing Control of Your Systems
Most teams that read this far know the gap isn’t understanding lineage concepts. It’s finding the hours to instrument dozens of pipelines while still shipping features. The approach involves embedding AI systems inside existing tools so the lineage graph, the validation logic, and the governance handover all live in systems the team already controls.
That embedded approach covers the practical steps this guide walks through: connecting automated capture to your orchestration and warehouse layer, validating the resulting graph against what your domain owners actually expect, and training your platform team to maintain it without ongoing dependency on outside help. Projects typically start with a scoped audit of your highest-priority pipelines, the same prioritization principle covered above, before moving into the actual embedded AI system build. If your pipelines involve heavier workflow automation needs alongside lineage, that gets scoped in the same engagement. Reach out through the services page to talk through where your data estate stands today and what a working lineage graph would look like in your specific stack.
FAQ
What Is the Best Data Lineage Tool?
There’s no single best tool; the right choice depends on your stack, with pipeline-native options fitting teams built around dbt or Airflow, lightweight PROV-JSON tools like dataprov suiting file-based reproducibility needs, and enterprise catalogs suiting organizations needing broad, cross-system coverage. Evaluate based on which capture methods (query parsing, CDC, API-driven) actually match your existing infrastructure.
What Is the Difference Between Data Lineage and Data Tracing?
Data lineage is the recorded map of where data came from and how it transformed, while data tracing (or traceability) is the operational capability of following that map to answer a specific question, like locating the source of a bad number in a report. Lineage is the record; tracing is the act of using it.
What Is the Role of Data Lineage in Master Data Management?
In master data management (MDM), lineage tracks how a golden record was assembled from multiple source systems and which transformations were applied, making it possible to explain discrepancies between the master record and any single source system. This is especially important when regulators or auditors question which system’s data took precedence.
Can You Give an Example of Data Lineage?
A customer’s email address might originate in a CRM, flow through an ETL job into a data warehouse table, get joined with marketing data in a transformation script, and finally land in a dashboard metric. Column-level data lineage tracking would record every one of those steps, so if the dashboard shows a wrong count, an engineer can trace backward through each transformation to find exactly where the error was introduced.