AI Resume Screening: How I Would Rebuild It So the Rejections Stay Auditable
AI resume screening compliance turns on the rejection set: the candidates a model filtered out and nobody read. A teardown of the workflow and the record it should keep.
On this page
Direct Answer
AI resume screening compliance is a record-keeping problem before it is a model problem. The system’s real output is not the shortlist a recruiter reads. It is the much larger set of applications nobody opened, because a score placed them below a line. If the workflow cannot reconstruct why each of those was filtered out, and show that a named person had the authority to disagree, there is no audit to run.
Key Takeaways
- Under Annex III of the EU AI Act, AI used to analyse and filter job applications and to evaluate candidates is a high-risk system. Those obligations were deferred to 2 December 2027, not removed.
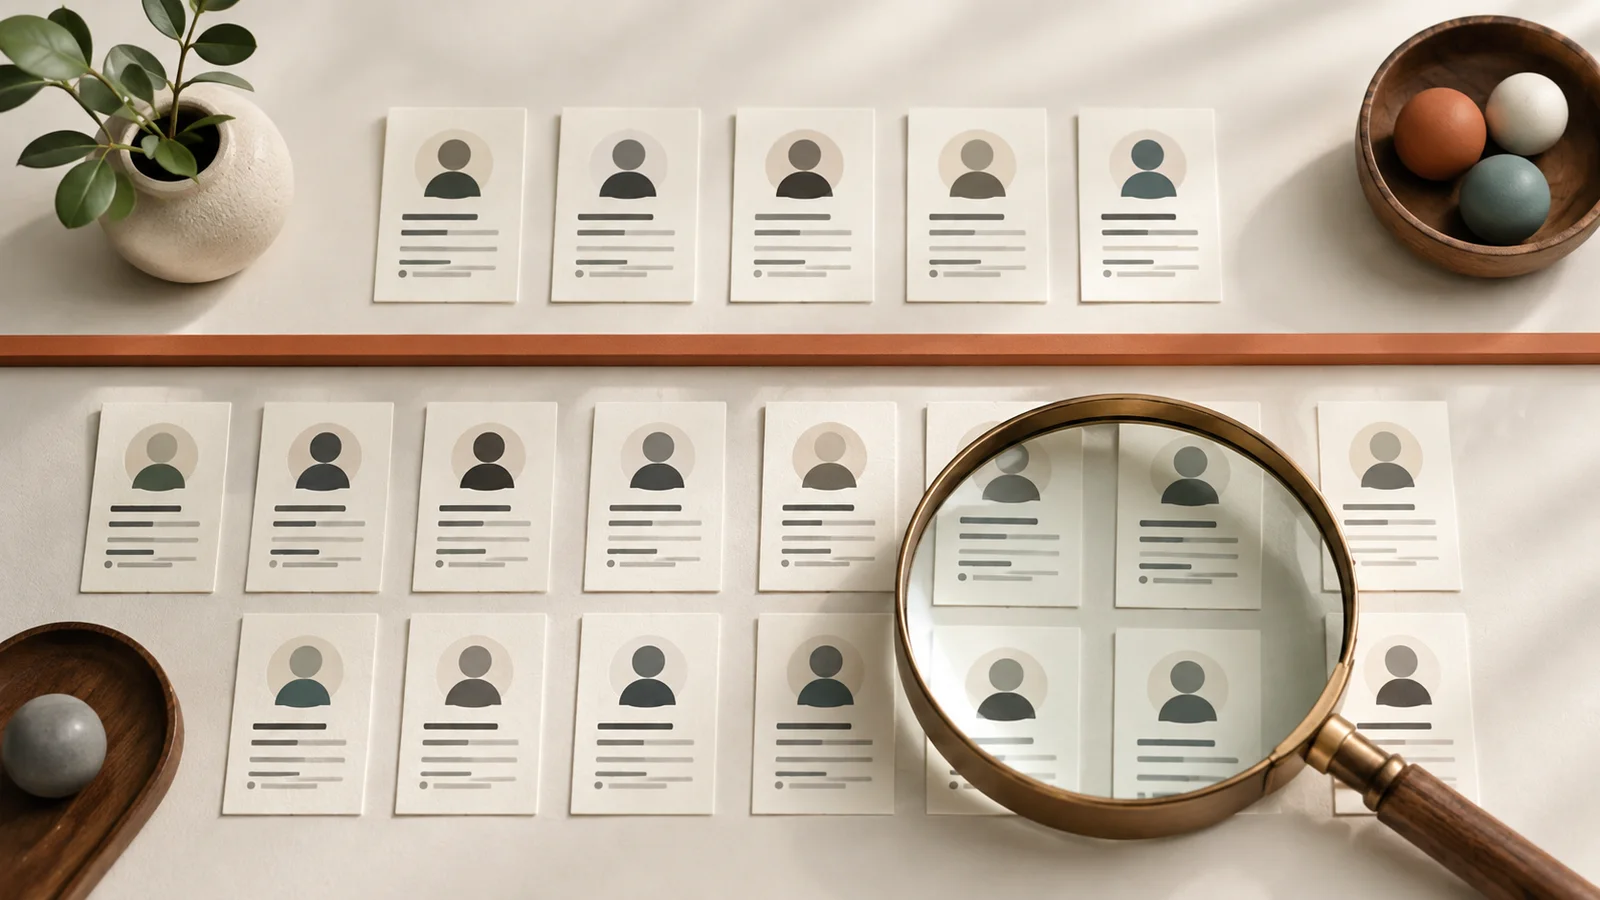
- The compliance artefact is the rejection set: the ranked candidates a human never opened, together with the evidence that put them there.
- Article 26(2) requires the person exercising oversight to have competence, training and authority. A reviewer who only ever reads page one of a ranked list has presence, not authority.
- New York’s enforcement record shows what thin evidence produces. The city regulator reviewed 32 companies and identified one instance of non-compliance; state auditors reviewing the same companies identified at least 17.
What problem does this system actually own?
A screening system owns the boundary between filtering and deciding, and at volume that boundary does not exist.
Vendors are careful here, and the care is accurate. Screening tools describe themselves as ranking or surfacing candidates rather than rejecting them, because a recruiter still clicks. That description is technically true and operationally hollow. When several hundred applications arrive for one opening and the reviewer works down a ranked list until the interview calendar fills, the model chose the cut-off. The click confirmed it.
This is the same shape as the prior authorization system that never signs the denial: a system that never issues the refusal can still make the refusal inevitable, by controlling what reaches the person who signs. Hiring has that shape with weaker paperwork. A denied claim produces a letter with a reason attached to it. A candidate who lands below the fold of a ranked list produces nothing at all.
This is not an argument that the ranking is biased. It might be, and a bias audit is one way to find out. The argument is narrower. Most screening stacks cannot produce the evidence that would settle the question in either direction, because the losing half of the output is never recorded as a decision. It is recorded as an absence.
The existing workflow I would map first
Before designing anything I would trace the route an application actually takes, including the parts nobody documents.
An application arrives through a job board or a careers page. The applicant tracking system parses it into fields, and the parse is lossy in ways nobody logs: a two-column PDF the parser reads out of order, a date format it interprets as an employment gap. A matching step scores the parsed record against a requisition someone wrote quickly, often by copying last year’s. A ranked list appears. A recruiter reviews the top of it. Everyone below the fold moves into a status meaning “not progressed” and, at most companies, into a rejection email fired by a rule.
Then the record settles. The outcome is kept. The ranking evaporates.
| Step | What happens today | Where it breaks |
|---|---|---|
| Parse | Resume converted into structured fields | Parse errors are silent, so a mangled date becomes a real signal |
| Requisition | Criteria copied from an earlier posting | The model optimises against requirements nobody currently defends |
| Score and rank | Candidates ordered by fit | The score is stored as a number, not as the evidence behind it |
| Review | Recruiter works down the list | Review depth moves with workload, and nothing records where they stopped |
| Rejection | Bulk status change plus templated email | No per-candidate reason exists, so there is nothing to audit or appeal |
| Retention | Outcome kept, ranking discarded | The record a regulator or a claimant would ask for is the one nobody kept |
Every one of those steps predates AI, and most of them were fine when a person read every application. The scoring step is what changed. It moved the cut-off from a human’s attention span to a number, and the record-keeping never followed.
How the system would run
The design change is easy to state and awkward to implement: treat every filtered-out application as a decision that owes a reason, on the same terms as an offer.
One requisition object, versioned. Criteria live in a structured record with an owner and a version, not in prose in a job advert. When someone edits “5 years experience” to “3 years”, that edit has a timestamp and a name attached, and every candidate scored under the old version is still traceable to it.
A score that carries its evidence. A candidate’s position stores the criteria matched, the spans of text that matched them, the criteria missed, and the parse confidence for each field involved. A number on its own explains nothing six months later, which is exactly when it gets asked about.
An explicit cut-off, set by a person. Somebody chooses to review the top forty, and that choice is logged with their name and the reason. Today the cut-off is emergent: it is wherever the recruiter ran out of Thursday. Making it explicit is the single change that converts a drift into a decision.
A rejection set that can be queried. Of the candidates cut this month, how many were cut on exactly one criterion? Which criterion moved the most people? Where did parse confidence fall below threshold, and did anyone look at those applications by hand?
None of that needs a better model. It needs the system to write down what it already computed. Most tools discard the intermediate because retaining scores felt like retaining a liability. That instinct is now backwards. From 2 December 2027, deployers of high-risk systems in the EU must keep the logs a system generates automatically for at least six months, unless other law says otherwise. The absence of a record stops working as protection.
What stays under human control?
Three things, and none of them is “reviewing the shortlist”.
The cut-off stays human, because it is the decision that determines the size of the rejection set. The criteria stay human, because a requisition is a claim about what the job requires and somebody has to defend it. The exception path stays human, and it needs to be a real path: a reviewer who spots a strong candidate below the line must be able to pull them up and have that override recorded as a signal about the ranking, not as a private favour.
Article 26(2) is unusually direct about the standard. Deployers must assign oversight to people with the necessary competence, training and authority. Authority is the operative word. A recruiter who can advance a candidate but cannot pause a requisition, change a criterion, or reject the ranking has been given a view, not oversight. That distinction runs through most of what I write about where human-in-the-loop actually belongs, and hiring is where it is easiest to fake.
How I would measure the path
Not time-to-hire. Time-to-hire improves the moment you read fewer applications, which is precisely the behaviour under examination.
Reconstruction rate. Take twenty rejected applications at random from last quarter and try to explain each outcome using only what the systems retained. The proportion you can explain is your actual compliance position. If it is low, the logging is decoration.
Override rate, per reviewer. How often does a human move a candidate across the cut-off? A rate of zero across an entire team is not evidence of a good model. It is evidence that nobody believes disagreeing is part of their job.
Single-criterion cuts. The share of rejections that turn on exactly one missed criterion. A high share tells you the requisition is doing the filtering, not the assessment, and requisitions are where copied assumptions accumulate.
There is one more, and it is the commercially interesting one: how many rejected candidates would a hiring manager reverse if shown the evidence? That number is the cost of the current cut-off. Almost nobody measures it, because almost nobody kept the set.
When this is the wrong build
If a role attracts a few dozen applications, this is overhead. The bottleneck is sourcing, not filtering, and adding a scoring layer with an audit trail solves a problem you do not have. Screening systems earn their place at volumes where reading everything is genuinely impossible.
It is also the wrong build if the organisation wants the ranking to stay unaccountable. A system that records its rejections is a system that can be argued with, internally by a hiring manager and externally by a candidate. That is the point, and it is a real cost. Better to be honest about wanting it than to buy an audit trail nobody intends to open.
A bias audit is not this either. New York City’s Local Law 144 requires a bias audit conducted no more than a year before the tool is used, a published summary of the results, and notice to candidates before an automated tool evaluates them, with civil penalties between $500 and $1,500 per day for violations. A bias audit is a statistical check on selection rates across groups. It describes the aggregate shape of the output and cannot say why any individual was cut. The rejection set is the per-candidate layer underneath. Neither one substitutes for the other.
The enforcement record is worth reading before deciding how much of this is theatre. In a December 2025 audit of the city’s enforcement, New York State auditors reported that the Department of Consumer and Worker Protection had surveyed 32 companies and identified a single instance of non-compliance, while the auditors reviewing those same companies identified at least 17. Weak enforcement is not an argument for weak evidence. It is a sign that the evidence available today is poor enough that the regulator cannot see through it either.
How this connects to the engagement
The teardowns here keep arriving at the same structural point from different industries. In insurance claims and in contract review, the model reads faster than a person and that is not where the value sits. The value sits in what the system records about its own uncertainty, and in who is permitted to act on it. The same question runs through what an AI-native compliance workflow would look like.
Hiring is where that argument is easiest to wave away and hardest to avoid. Easiest, because screening feels like sorting rather than deciding. Hardest, because the person on the other side of the cut-off has no visibility, no route of appeal, and, from 2 December 2027 in the EU, a regulator who is entitled to ask for the file. The Digital Omnibus deferral moved that date by sixteen months. It did not change what the file has to contain.
If you already run AI-assisted screening, the first useful exercise costs nothing. Take last month’s rejections, pick twenty, and try to explain them from your own systems. Whatever you find is the honest starting point.
Summary
Screening systems get judged on the shortlist and audited on the rejections, and the distance between those two facts is where the work is. Build the rejection set as a first-class output (versioned criteria, scores that carry their evidence, a cut-off a person chose, a record you can query) and the compliance file falls out of a system worth having regardless of any regulation.
I have not built this against a live applicant tracking system, and the design is not the hard part. The hard part is that most of these systems never expose the intermediate scores at all. Which makes the first question for a vendor something other than how good the ranking is. It is whether you can get the ranking out.
Frequently asked questions
Is AI resume screening legal under the EU AI Act?+
Yes. Annex III classifies AI used for the recruitment or selection of people as high-risk rather than prohibited. Obligations for stand-alone Annex III systems now apply from 2 December 2027 after the Digital Omnibus deferral, and deployers carry duties of their own, including human oversight and log retention.
What is a rejection set in AI resume screening?+
It is the group of applications a screening model ranked below the cut-off and no human opened, together with the evidence that produced each position: criteria matched and missed, the text that matched them, and parse confidence. Most applicant tracking systems keep the outcome and discard the evidence.
Does a bias audit cover per-candidate rejections?+
No. A Local Law 144 bias audit reports selection and scoring rates across sex, race and ethnicity categories. It describes the aggregate shape of the output and cannot explain why any individual candidate was filtered out.
How long do AI screening logs have to be kept?+
Article 26(6) of the EU AI Act requires deployers of high-risk AI systems to keep automatically generated logs for at least six months, unless other Union or national law provides otherwise. Separately, a New York City bias audit must be no more than one year old when the tool is used.
Does a recruiter clicking reject count as human oversight?+
Not on its own. Article 26(2) requires oversight by people with the necessary competence, training and authority. If the reviewer cannot change the criteria, move the cut-off, or overrule the ranking, the click is confirmation rather than oversight.
Sources
- EU AI Act, Annex III: High-Risk AI Systems
- EU AI Act, Article 26: Obligations of Deployers of High-Risk AI Systems
- EU AI Act Implementation Timeline (Future of Life Institute)
- NYC Department of Consumer and Worker Protection: Automated Employment Decision Tools
- Office of the New York State Comptroller, Enforcement of Local Law 144 (Audit 2024-N-6)
- Gibson Dunn: EU AI Act Omnibus Agreement, Postponed High-Risk Deadlines